Fine-tuning
Domain adaptation and performance improvement using your data and task requirements.
Deployment, optimization, and global compute services.
Access leading open models through OpenAI-compatible APIs, adapt models to your domain, and lease dedicated compute for training, fine-tuning, and inference—all through one enterprise-oriented delivery path.
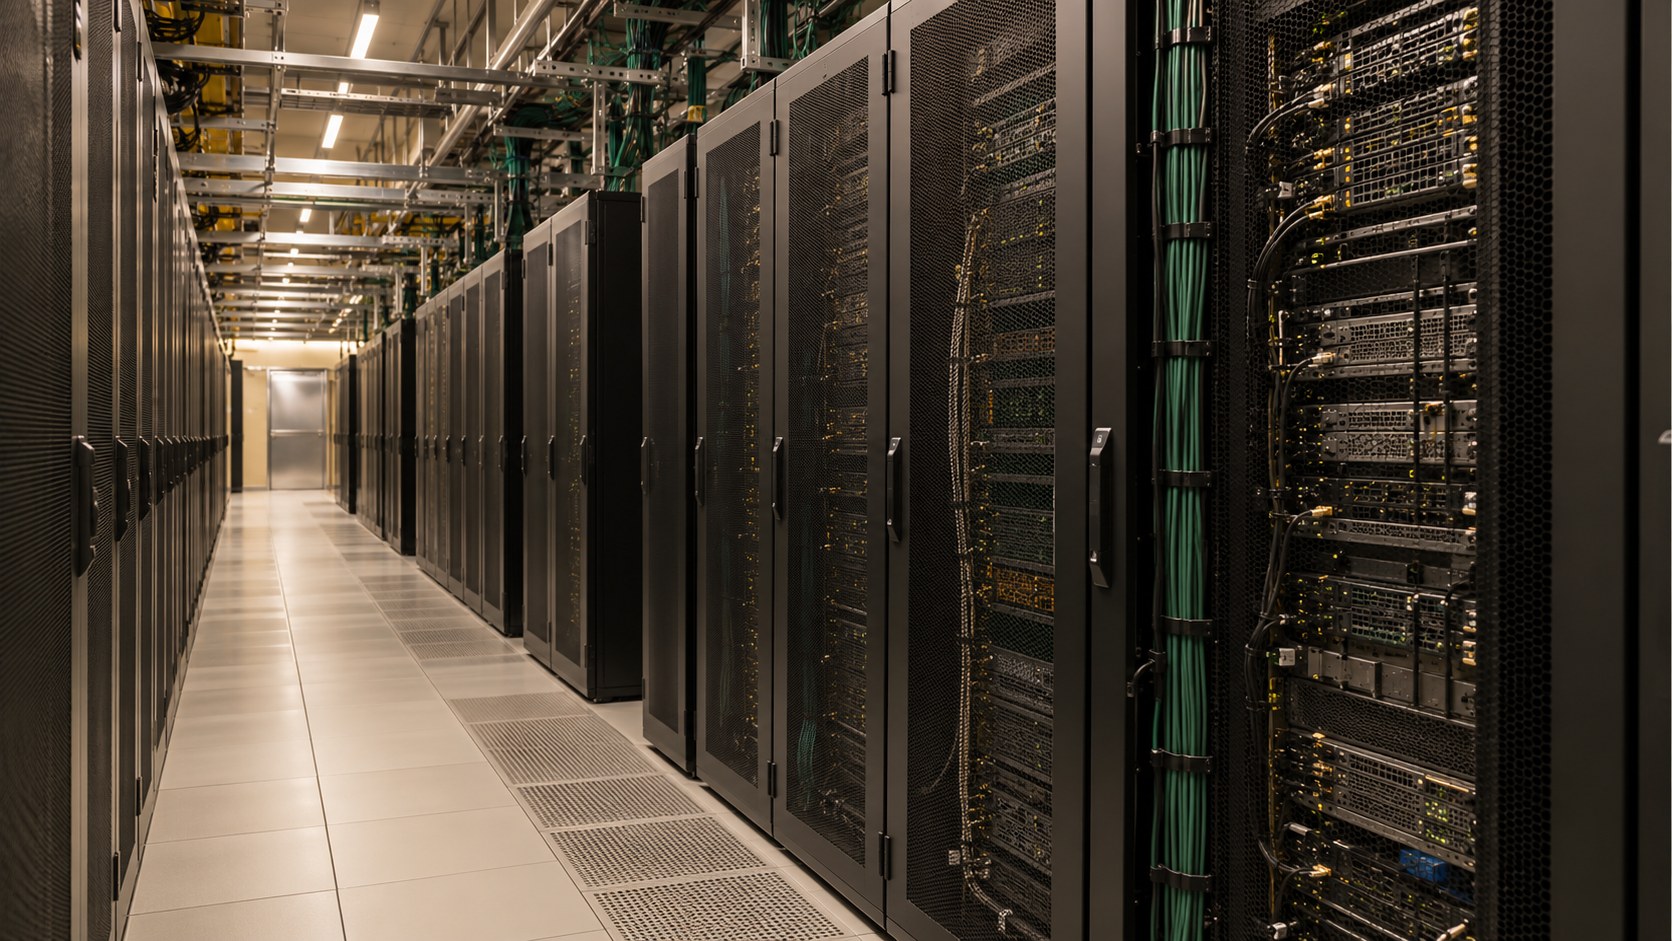
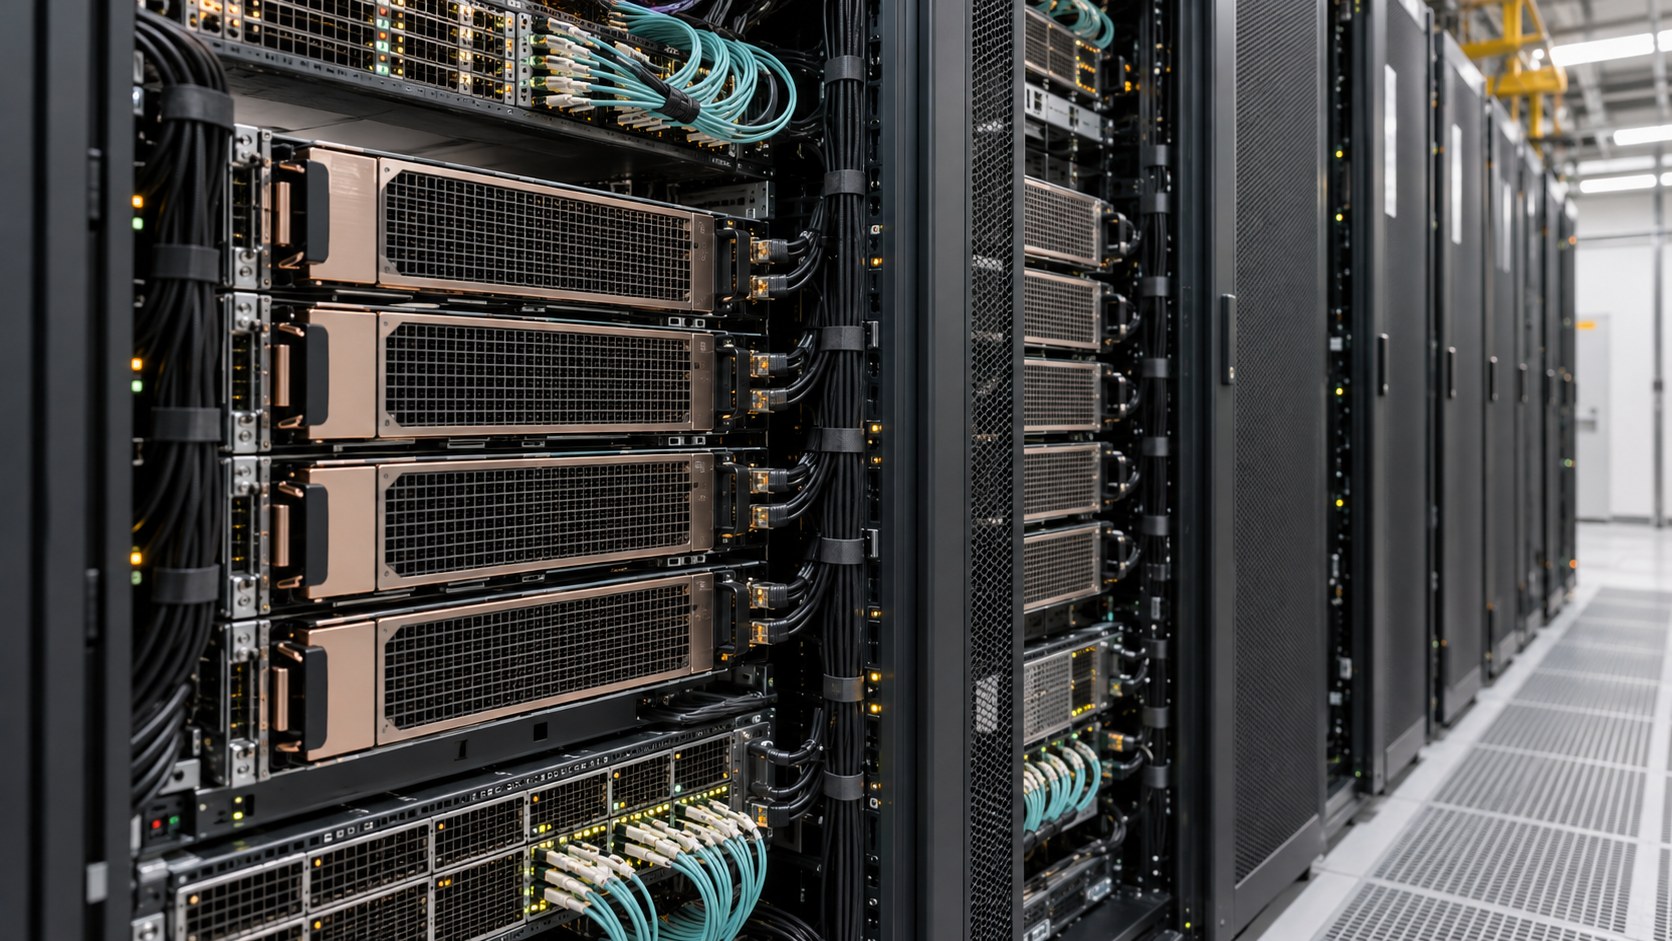
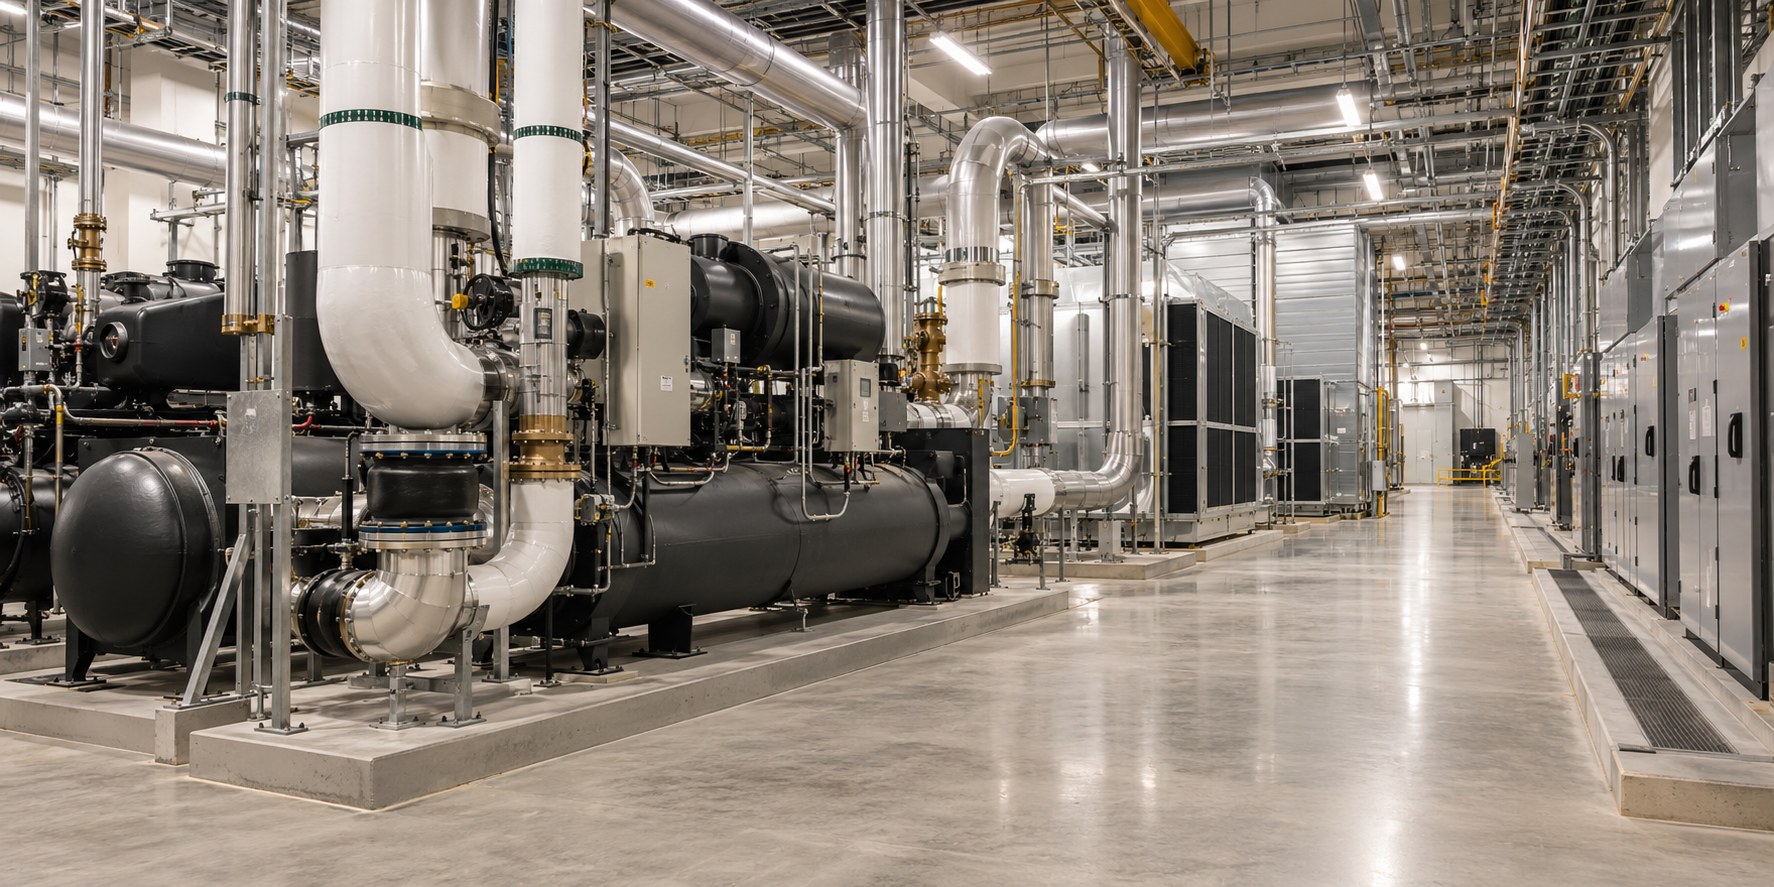
Illustrative facility imagery. Site-specific hardware, capacity, and availability are confirmed for each engagement.
OpenAI-compatible API endpoints for leading open models, prepared for global deployment with predictable performance and a lower cost profile.
Compared with public API pricing for selected models
We tailor open models to domain requirements, latency targets, cost efficiency, and quality objectives—then evaluate them against real tasks.
Domain adaptation and performance improvement using your data and task requirements.
SFT, RLHF, DPO, and continued pre-training to align model behavior with intended use.
Model compression to reduce inference cost and support higher throughput.
INT8/INT4 and advanced quantization techniques for efficient deployment.
Smaller, faster models designed to retain the capabilities that matter for the task.
Improve latency, throughput, and cost for production workloads.
Comprehensive evaluation and testing on representative real-world tasks.
On-premises and VPC deployment options for sensitive workloads and data.
Dedicated, global, self-built compute capacity for training, fine-tuning, and inference—from single-GPU workloads to multi-node clusters.
Dedicated clusters and flexible compute resources for workloads of different scales.
High-speed networking, storage, and workload scheduling for training and large-scale inference.
Regional deployment options aligned to workload, latency, and data requirements.
Dedicated clusters or multi-tenant options with enterprise-grade isolation.
The poster states 50,000P+ of global self-built compute capacity across its infrastructure footprint.
Self-built data centers are designed to reduce exposure to compute price volatility and support long-term delivery.
Capacity, hardware availability, region, and lease terms are confirmed against the requested configuration and delivery window.
Research and engineering experience, compute partnerships, and end-to-end delivery help teams move from model selection to production infrastructure.
Team backgrounds spanning MIT, Stanford, and Tsinghua, combined with practical model and infrastructure work.
Strategic partnerships intended to broaden compute coverage and available capacity.
Support from model adaptation and optimization through production deployment and infrastructure.
Experience across AI infrastructure, distributed systems, model deployment, and optimization.
Lower total cost through a balance of reliability, workload fit, and measurable business value.
Infrastructure ownership and operations designed to support more stable supply and pricing.
Security and deployment controls can be selected to match enterprise workloads, private deployments, and sensitive data handling requirements. Exact controls are agreed during solution design.
For enterprise proposals, customized pricing, private deployment, or benchmark-based optimization plans, contact us for a tailored solution.